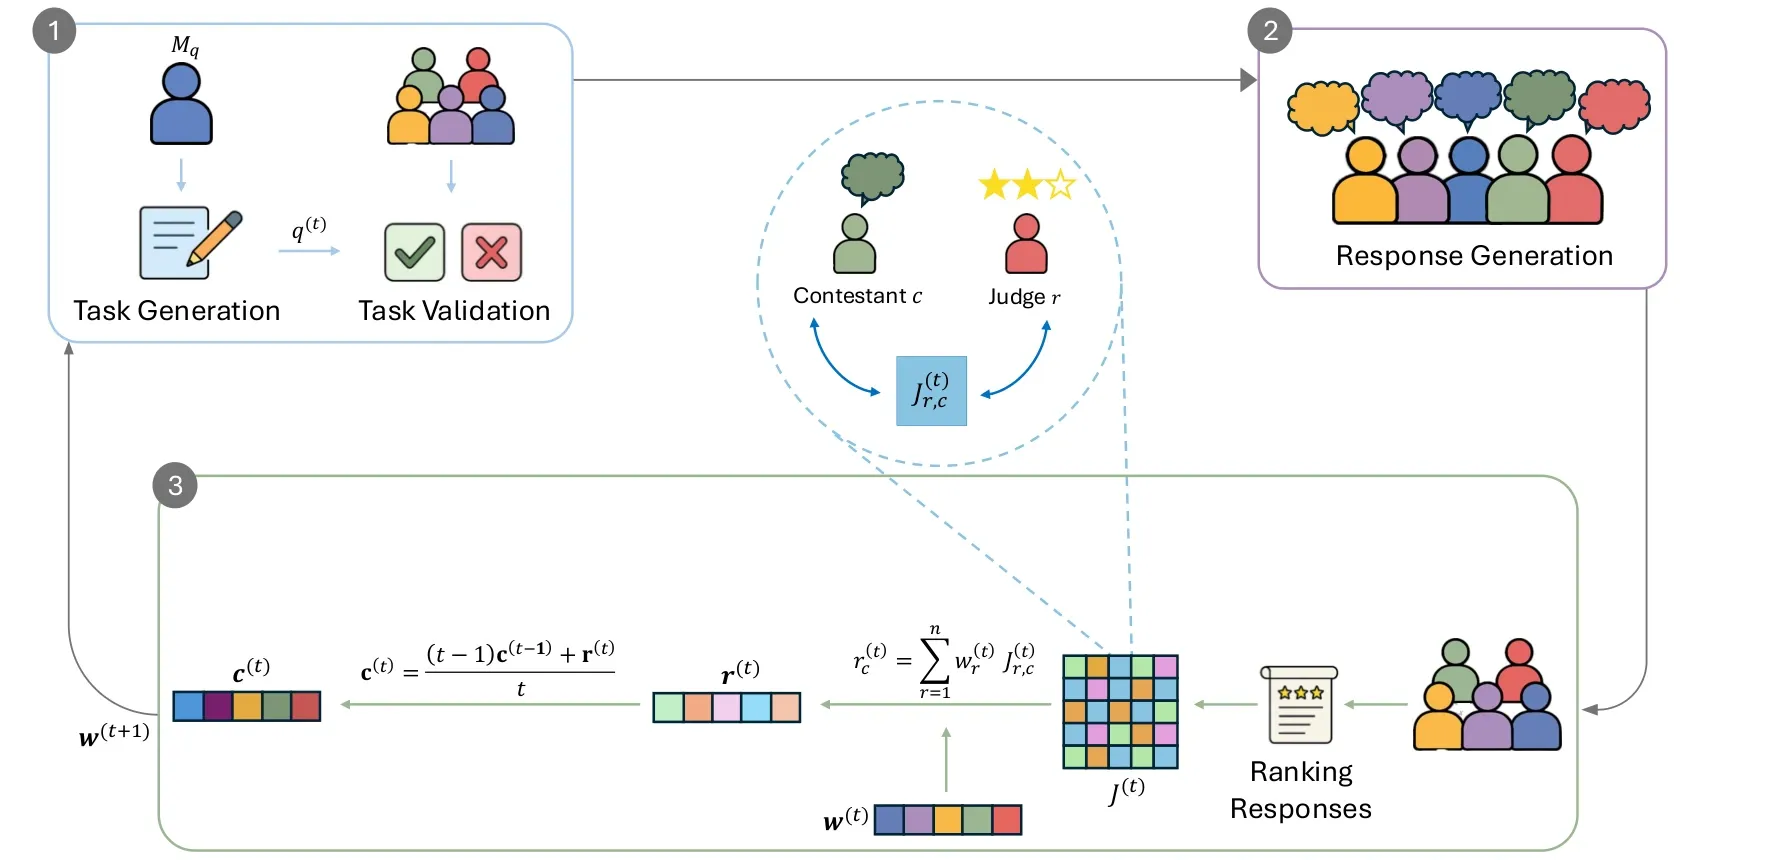
In short Language models take turns writing tasks, answering them, and judging each other's answers. Weighting each judge by its reliability gives rankings that correlate with MMLU-Pro (78%) and GPQA (63%).
Abstract
We present AutoBench, a fully automated and self-sustaining framework for evaluating Large Language Models (LLMs) through reciprocal peer assessment. This paper provides a rigorous scientific validation of the AutoBench methodology, originally developed as an open-source project by eZecute S.R.L. Unlike static benchmarks that suffer from test-set contamination and limited adaptability, AutoBench dynamically generates novel evaluation tasks while models alternately serve as question generators, contestants, and judges across diverse domains. An iterative weighting mechanism amplifies the influence of consistently reliable evaluators, aggregating peer judgments into consensus-based rankings that reflect collective model agreement. Our experiments demonstrate strong correlations with established benchmarks including MMLU-Pro and GPQA (respectively 78% and 63%), validating this peer-driven evaluation paradigm. The multi-judge design significantly outperforms single-judge baselines, confirming that distributed evaluation produces more robust and human-consistent assessments. AutoBench offers a scalable, contamination-resistant alternative to static benchmarks for the continuous evaluation of evolving language models.
Cite
@misc{loi2025autobench,
  title         = {{AutoBench}: Automating {LLM} Evaluation through Reciprocal Peer Assessment},
  author        = {Dario Loi and Elena Maria Mui{\`a} and Federico Siciliano and Giovanni Trappolini and Vincenzo Cris{\`a} and Peter Kruger and Fabrizio Silvestri},
  year          = {2025},
  eprint        = {2510.22593},
  archivePrefix = {arXiv},
  primaryClass  = {cs.CL},
  url           = {https://arxiv.org/abs/2510.22593}
}