Implicit Inversion turns CLIP into a Decoder
- 1 OmnAI Lab, Sapienza University of Rome
- 2 GLADIA, Sapienza University of Rome
The Fourteenth International Conference on Learning Representations (ICLR 2026), Poster
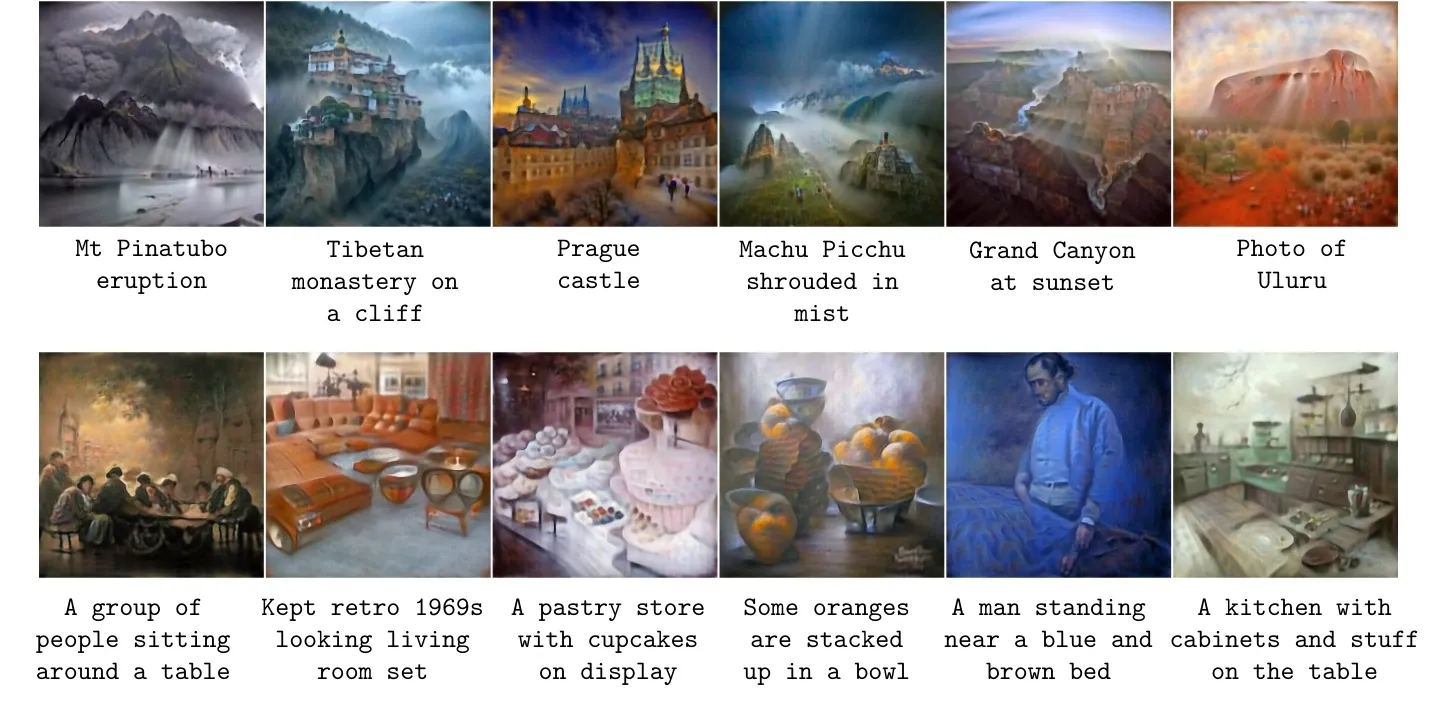
In short A frozen CLIP, run backward through an implicit neural representation, generates images from text with no decoder and no fine-tuning. The same setup supports style transfer, image editing, and probing what CLIP encodes.
Abstract
CLIP is a discriminative model trained to align images and text in a shared embedding space. Due to its multimodal structure, it serves as the backbone of many generative pipelines, where a decoder is trained to map from the shared space back to images. We show that image synthesis is nevertheless possible using CLIP alone, without a pre-trained generative decoder or CLIP tuning. Our approach optimizes a frequency-aware implicit neural representation that encourages coarse-to-fine generation by stratifying frequencies across network layers. To stabilize this inverse mapping, we introduce adversarially robust initialization, a lightweight Orthogonal Procrustes projection to align local text and image embeddings, and a blending loss that anchors outputs to natural image statistics. With CLIP frozen, this framework unlocks capabilities such as text-to-image generation, style transfer, and image reconstruction. Our findings suggest that discriminative models may hold untapped generative potential, hidden in plain sight.
When a text-to-image system turns a prompt into a picture, two networks share the work. A decoder, usually a diffusion model, generates the pixels. A separate model encodes what the prompt means in visual terms. In many pipelines the second model is CLIP (Radford et al., 2021), which was trained to tell whether an image and a caption belong together. We asked what happens if CLIP is made to generate the image itself, by running it backward until an image matches the prompt.
A frozen CLIP, with no decoder and no further training, can produce recognizable images from text this way. In our view, these images measure how much visual structure a discriminative model already holds. They also probe how it behaves on inputs it was never meant to see.
Image generation without a decoder
CLIP inversion is a case of model inversion, i.e., treating a trained network as a fixed function and searching for the input that makes it respond in a chosen way. For CLIP, searching directly over pixels gives images with visible artifacts (Kazemi et al., 2024), and other decoder-free attempts avoid this only by training further or tuning CLIP itself. We leave CLIP alone and change what is being optimized.
Because the model stays frozen, every image is a readout of one specific checkpoint. That keeps the system small. With 40 optimization steps, an image takes 7.8 seconds and 3.2 GB of peak memory on an 8 GB RTX 4060, a card on which the latent diffusion baseline in that comparison (LDM-KL-8) ran out of memory. That makes training-free text-to-image synthesis look practical on commodity hardware, although we measured only the models in that comparison.
Why implicit neural representations help
An implicit neural representation (INR) stores an image as a function of coordinates, so the optimizer works on network weights instead of a grid of pixel values. This changes the problem in two ways. First, optimizing weights avoids the structural artifacts that pixel-space inversion produces. Second, a frequency-stratified network such as FINER exposes layers that correspond to coarse and fine detail, thus the optimizer can settle layout before texture. The paper describes the resulting generation order as akin to diffusion models, although nothing here is a diffusion process.
The remaining pieces address stability. Seeding the search from a blurred, weight-perturbed INR gives the first updates a solid place to start, which connects the work to adversarial robustness, where Mirza et al. (2024) suggest that robust models have stronger generative priors. The Procrustes step handles the modality gap, i.e., the offset between where CLIP places captions and where it places images (Liang et al., 2022). Aligning that offset locally per prompt is a lightweight step that leaves the model untouched.
Benchmark results
On 10,000 MS-COCO captions, our FID of 72.5 against 161.8 for Direct Ascent Synthesis puts decoder-free inversion in a different quality range from pixel-space methods, and the same holds for Inception Score (9.5 against 5.7). Diffusion models remain well ahead, with FIDs of 12.2 and 23.3, and they get there by training up to 6,000 million parameters. The comparison that matters for us is therefore among methods that keep CLIP frozen.
The CLIPSIM column shows a different pattern. CLIPInvert has the highest CLIPSIM (61.4) but an FID of 140.1, so it matches the embedding the optimizer was fitting without producing convincing images. The same pattern appears in our ablations, where dropping the Procrustes step or the blending loss raises CLIPSIM and produces cluttered scenes. Of the components we ablated, the frequency schedule costs the most when removed.
Interpreting vision-language models by drawing them
A decoder-free generator doubles as an interpretability tool. If CLIP is the only model in the loop, the picture that comes out reflects what CLIP's embedding encodes about the prompt. We used this on negations such as "this is not a photo of a dog" and on out-of-distribution prompts such as "an abstract and unrecognizable object", to see which visual cues are discriminative for CLIP and which become unstable outside its training distribution.
Stress-testing multimodal systems is a natural use. CLIP sits upstream of many pipelines, and its errors and biases travel with it. Rendering an embedding makes a failure visible before it is buried inside a larger system. The same property comes with a caution. Our generator inherits CLIP's societal biases and potential for misuse. In preliminary experiments with Safe-CLIP (Poppi et al., 2024), harmful content was blocked.
Editing, reconstruction and style transfer
The same pipeline runs without task-specific training on three further jobs. Reconstruction recovers an image from its CLIP embedding and gives a controlled test, because the ground truth is known. Prompt-driven editing starts from an INR fitted to a photo, so "snow" or "storm" adds weather while the geometry of a road or a city stays put, without any mask. For style transfer, the reference painting is passed only through the frozen CLIP encoder, and a content loss keeps the result tied to the photo. We read this as evidence that CLIP's embedding separates style from content. Readers searching for neural style transfer with CLIP will find a version built on the frozen CLIP encoder with no trained stylization network.
Where it goes next
Since all the regularization comes from the representation and the CLIP losses, a natural-image prior of modest size, or a projection onto the image manifold, is the direct route to sharper fine detail. The recipe can also be tried on other discriminative encoders, and inversion could become a routine audit for biased or brittle concepts in vision-language models before they reach larger pipelines.
References
- Stanislav Fort and Jonathan Whitaker (2025). Direct Ascent Synthesis: Revealing Hidden Generative Capabilities in Discriminative Models. arXiv preprint.
- Hamid Kazemi, Atoosa Chegini, Jonas Geiping, Soheil Feizi, and Tom Goldstein (2024). What do we learn from inverting CLIP models?. arXiv preprint (NeurIPS 2024 Safe Generative AI Workshop).
- Victor Weixin Liang, Yuhui Zhang, Yongchan Kwon, Serena Yeung, and James Zou (2022). Mind the Gap: Understanding the Modality Gap in Multi-modal Contrastive Representation Learning. Advances in Neural Information Processing Systems 35 (NeurIPS 2022).
- Zhen Liu, Hao Zhu, Qi Zhang, Jingde Fu, Weibing Deng, Zhan Ma, et al. (2024). FINER: Flexible Spectral-bias Tuning in Implicit NEural Representation by Variable-periodic Activation Functions. Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR 2024).
- Mujtaba Hussain Mirza, Maria Rosaria Briglia, Senad Beadini, and Iacopo Masi (2024). Shedding More Light on Robust Classifiers Under the Lens of Energy-Based Models. Computer Vision - ECCV 2024.
- Samuele Poppi, Tobia Poppi, Federico Cocchi, Marcella Cornia, Lorenzo Baraldi, and Rita Cucchiara (2024). Safe-CLIP: Removing NSFW Concepts from Vision-and-Language Models. Computer Vision - ECCV 2024.
- Alec Radford, Jong Wook Kim, Chris Hallacy, Aditya Ramesh, Gabriel Goh, Sandhini Agarwal, et al. (2021). Learning Transferable Visual Models From Natural Language Supervision. Proceedings of the 38th International Conference on Machine Learning (ICML 2021), PMLR 139.
Cite
@inproceedings{
dorazio2026implicit,
title={Implicit Inversion turns {CLIP} into a Decoder},
author={Antonio D'Orazio and Maria Rosaria Briglia and Donato Crisostomi and Dario Loi and Emanuele Rodol{\`a} and Iacopo Masi},
booktitle={The Fourteenth International Conference on Learning Representations},
year={2026},
url={https://openreview.net/forum?id=hvukI2ws5O}
}